Metadata
Sector
- Education
- Research
- AI
Scope
- Branding
- UI/UX Design
- Front-End Development
- Back-End Development
Harvard NeuroLaw Library
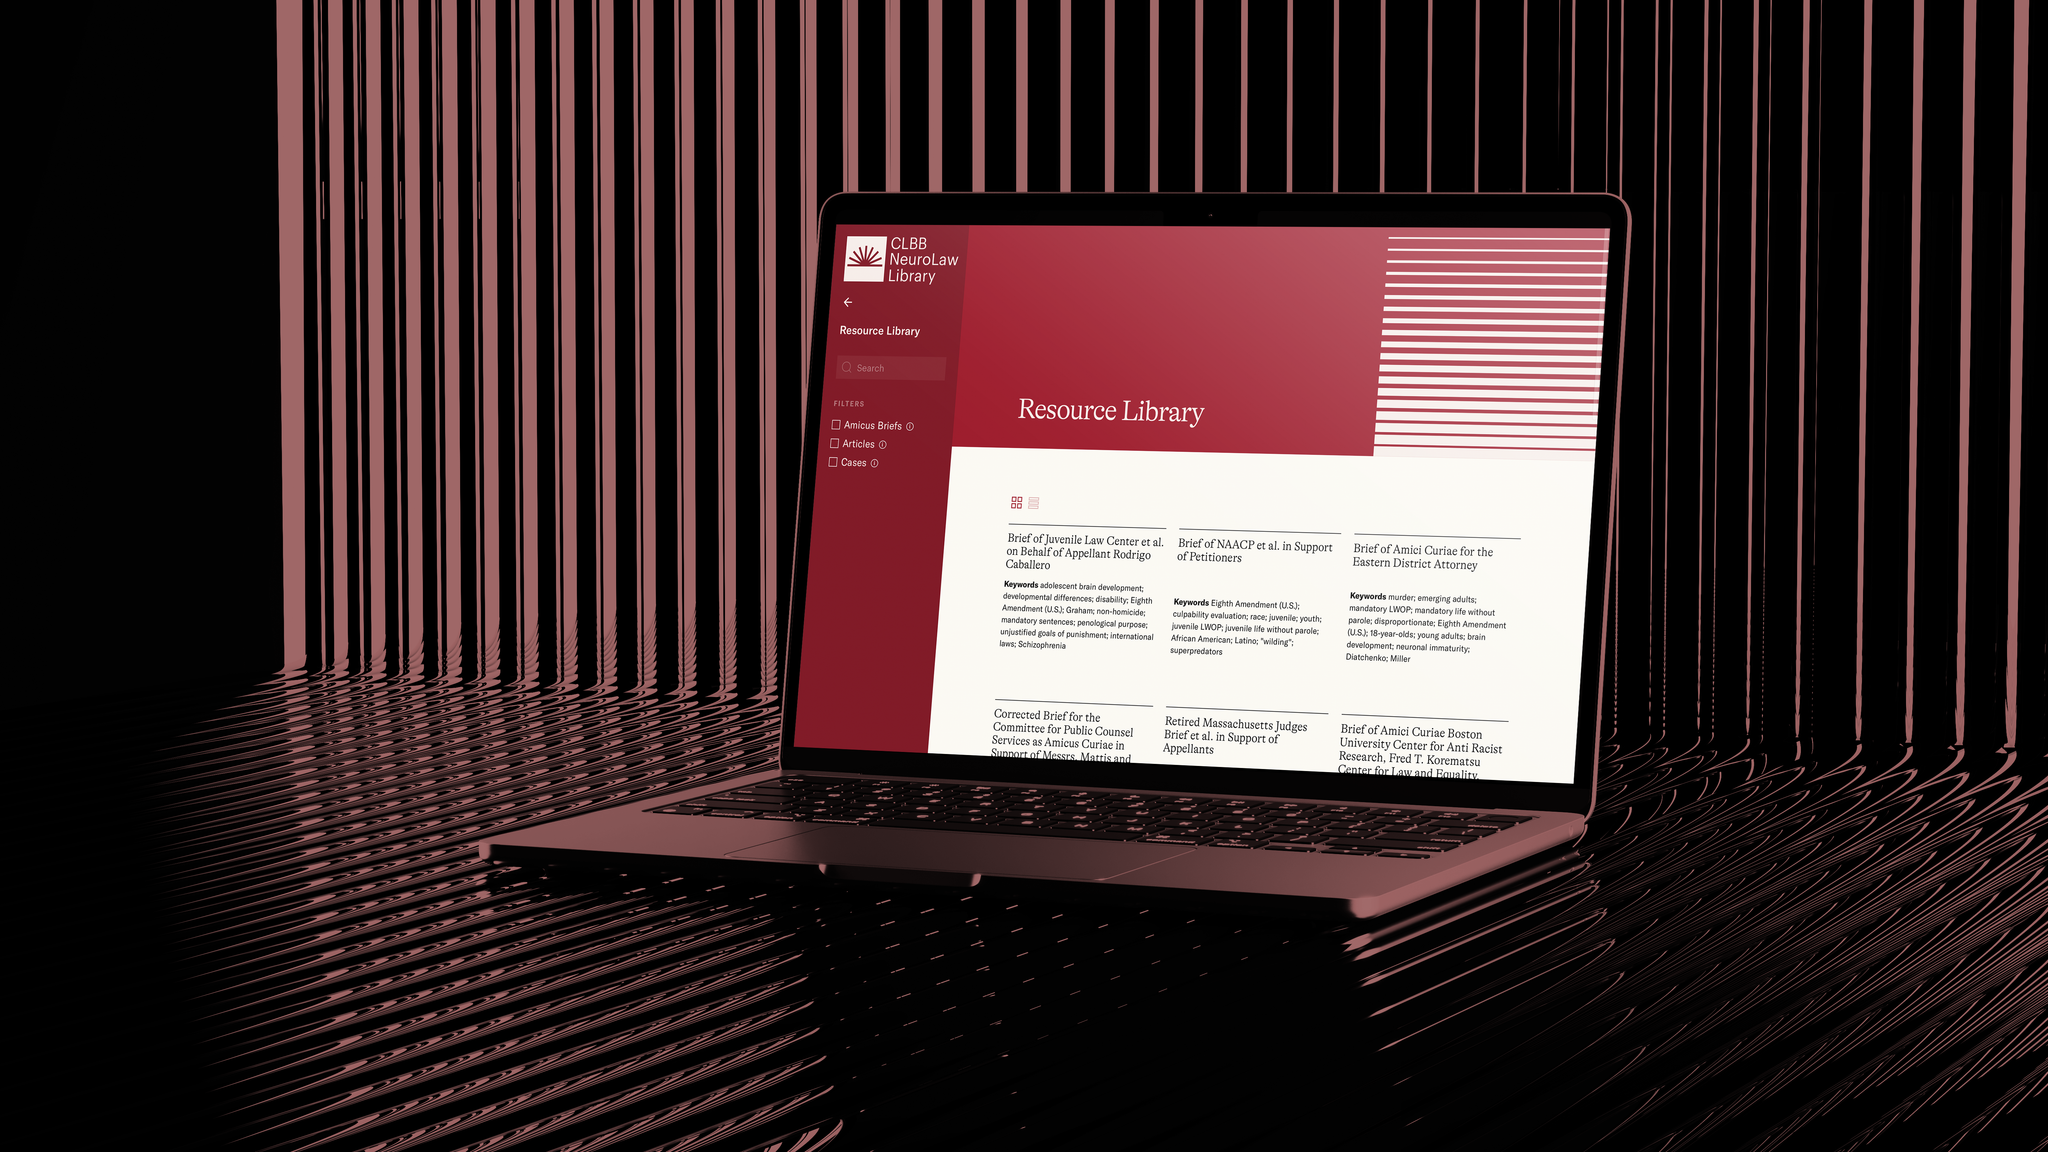
Harvard's CLBB NeuroLaw Library, run by the Center for Law, Brain and Behavior at Massachusetts General Hospital, is an open library of peer-reviewed articles, amicus briefs, court cases, and expert affidavits on neuroscience and law. Monogram designed and built it. Our role covered branding, UI/UX design, front-end and back-end development, LLM integration, and search. The stack is Next.js, React, Contentful over GraphQL, Typesense, Google Gemini 2.5 Flash, and Vercel. The library launched in 2024, and its AI pipeline, search, and review flow were rebuilt in August 2026. Every document is readable at five levels, the original plus four Gemini rewrites, behind one slider, with the original always one drag away.
Neuroscience shapes sentencing, competency rulings, and appeals, but it is written for journals. Defense attorneys, judges, clinicians, families, and incarcerated people all need it, and few can read it as published. Hand-writing simpler versions does not scale and goes stale on the next edit, and the content sat across four document types with different metadata, so searching it meant knowing what each thing was called.
Metrics
5
reading levels per document. The original plus four Gemini rewrites, behind one slider.
Thousands
of resources. Articles, amicus briefs, cases, and expert affidavits, each made multi-level automatically.
5
citation formats for every resource (APA · AMA · MLA · NLM · Bluebook).
Free
and fully public. No account, no paywall, no restriction.
Sector
- Education
- Research
- Legal
- AI
Scopes
- Branding
- UI/UX
- Front-end
- Back-end
- LLM integration
- Search
Technologies
- Next.js
- React
- Contentful
- GraphQL
- Typesense
- Google Gemini
- Vercel
The problem it removes
The audience is wide and the writing is narrow. Neurolaw research shapes sentencing, competency rulings, and appeals, and the people it affects include defense attorneys, prosecutors, judges, advocates, clinicians, families, and incarcerated people. The source material is dense, citation-heavy, and written at one expert reading level.
The old options were both bad: publish the original and lose most readers, or hand-write simpler versions that do not scale and go stale on the next edit. The goal was every document readable at the reader's level and the whole library searchable from one box.
Read it at your level
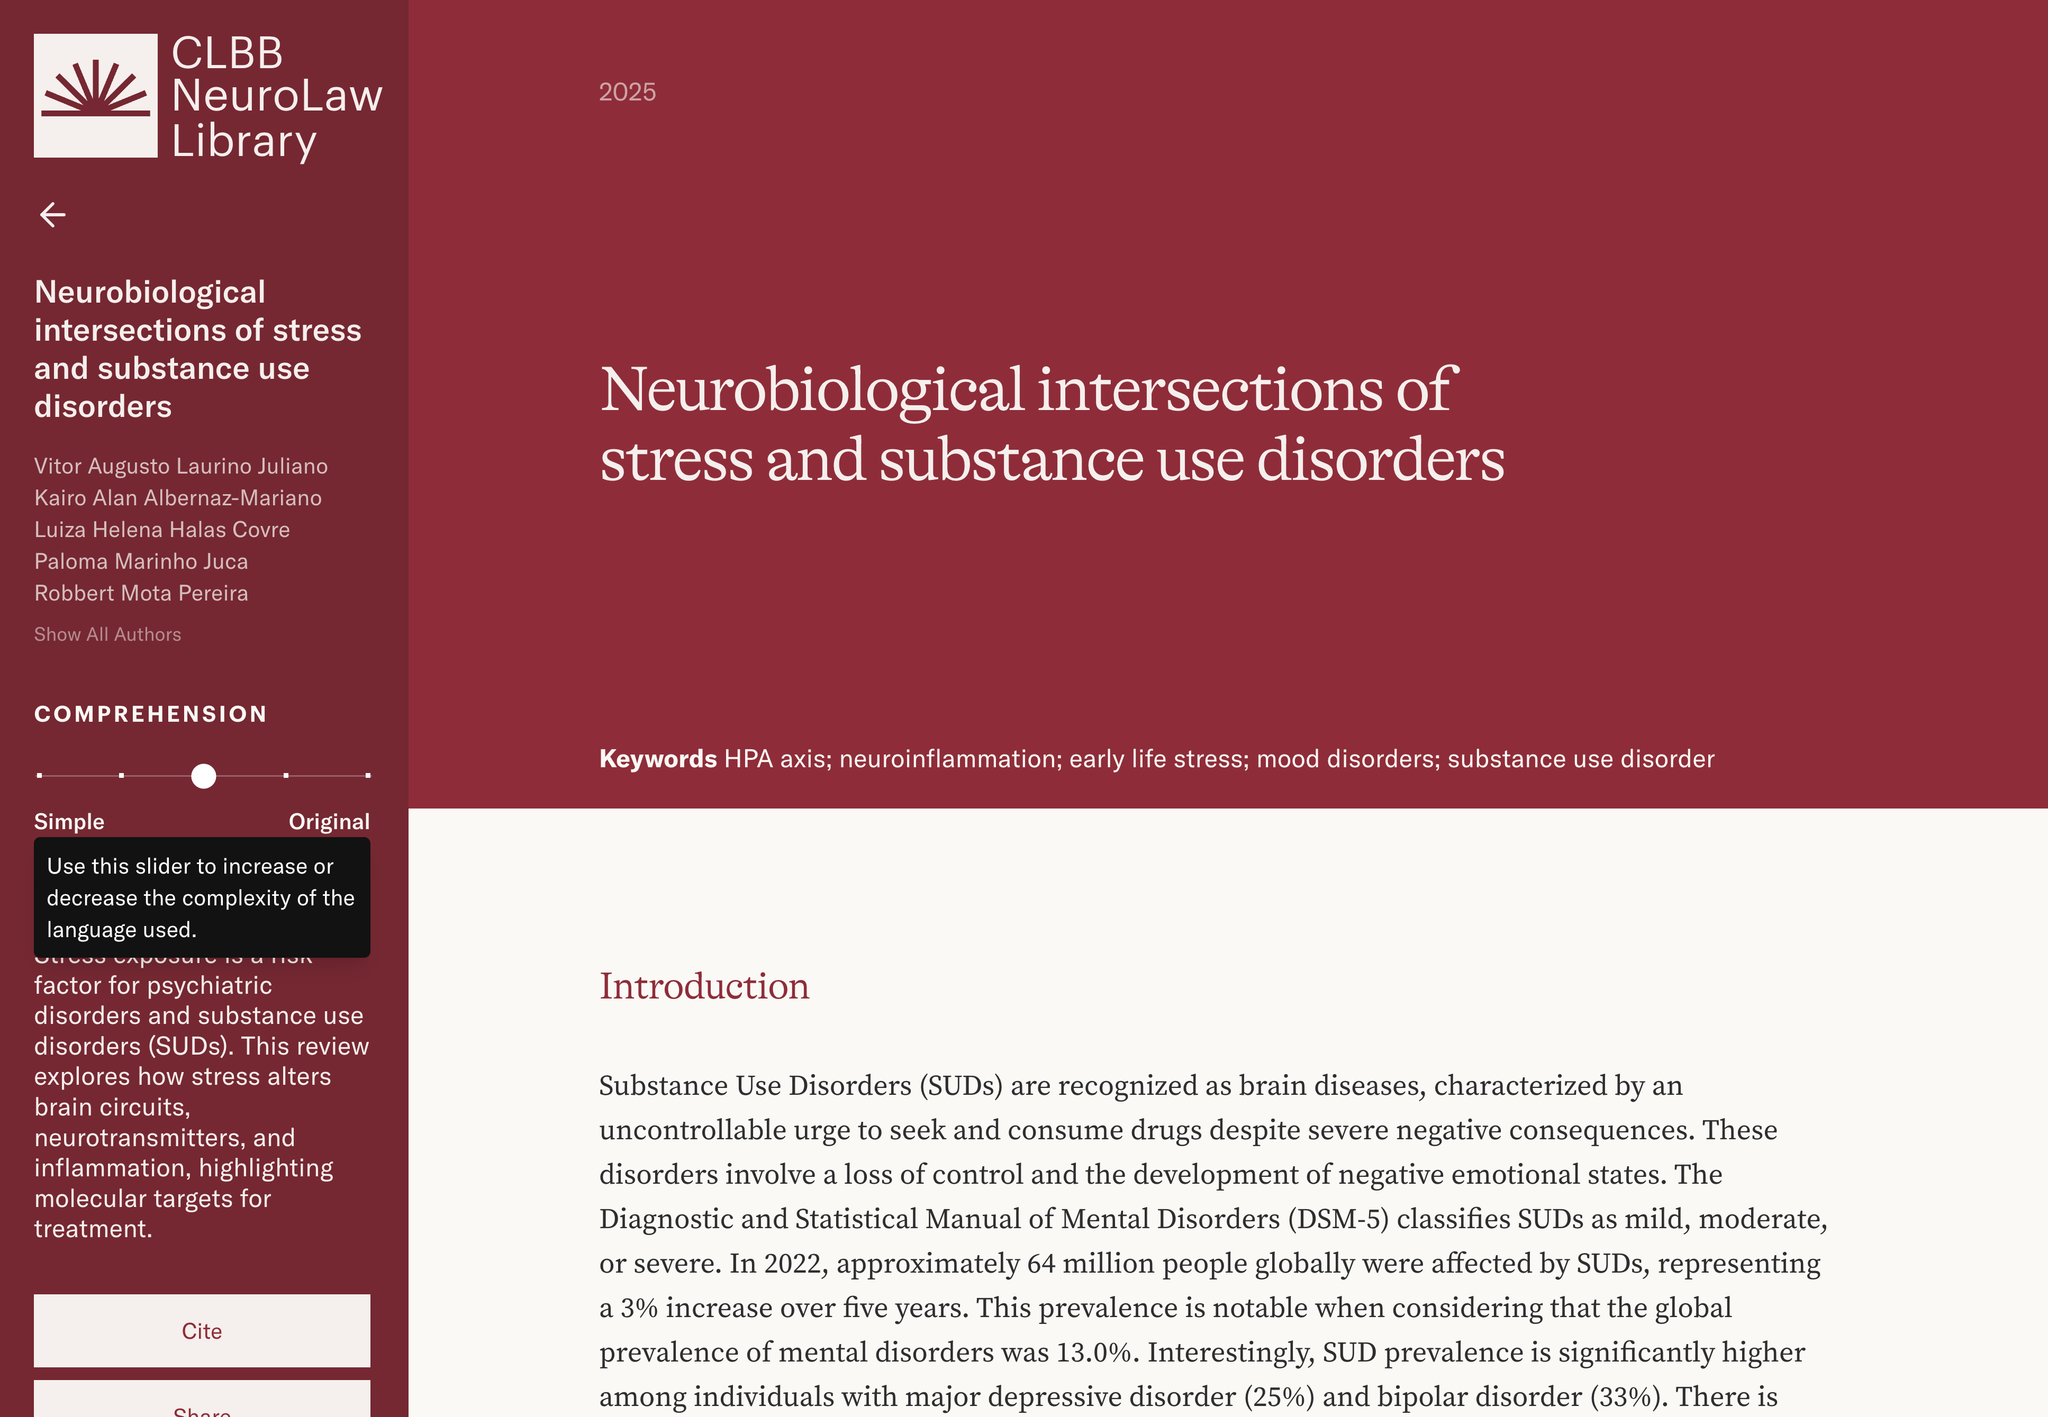
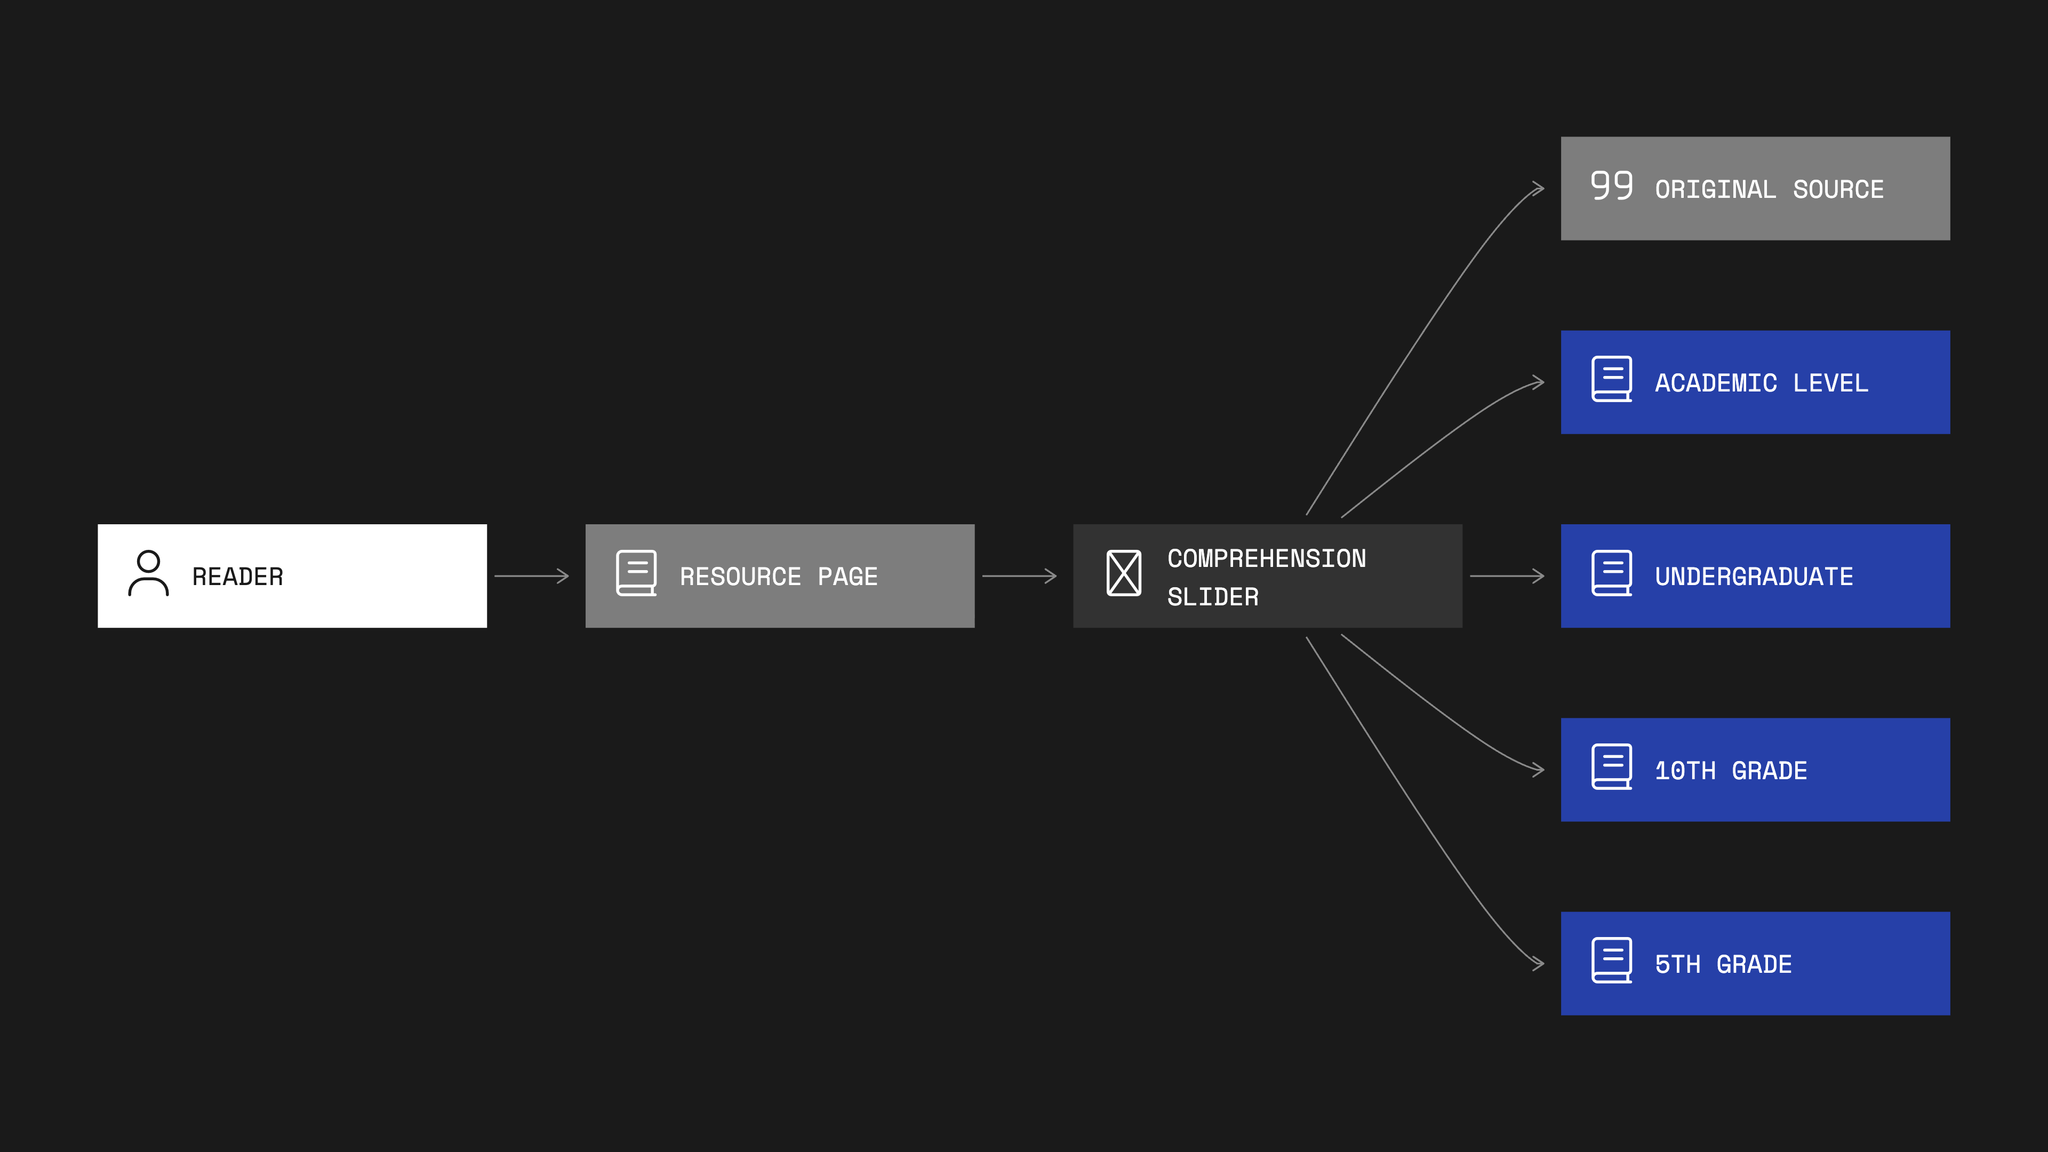
Open a document and you get a Comprehension Slider. Drag it and the same text re-renders at a different reading level, from the original down to plain 5th-grade language. Every level is generated ahead of time and stored at publish, so switching is instant. The original sits at the end of the slider, so the text you'd actually quote is always one drag away.
Original:
"Petitioner contends that the adolescent prefrontal cortex, being incompletely myelinated, materially impairs executive function and impulse control relevant to culpability."
Simplified:
"The teenage brain is still growing. The part that handles planning and self-control isn't finished yet, and that matters when deciding how responsible a young person is."
Generate once at publish, read for free
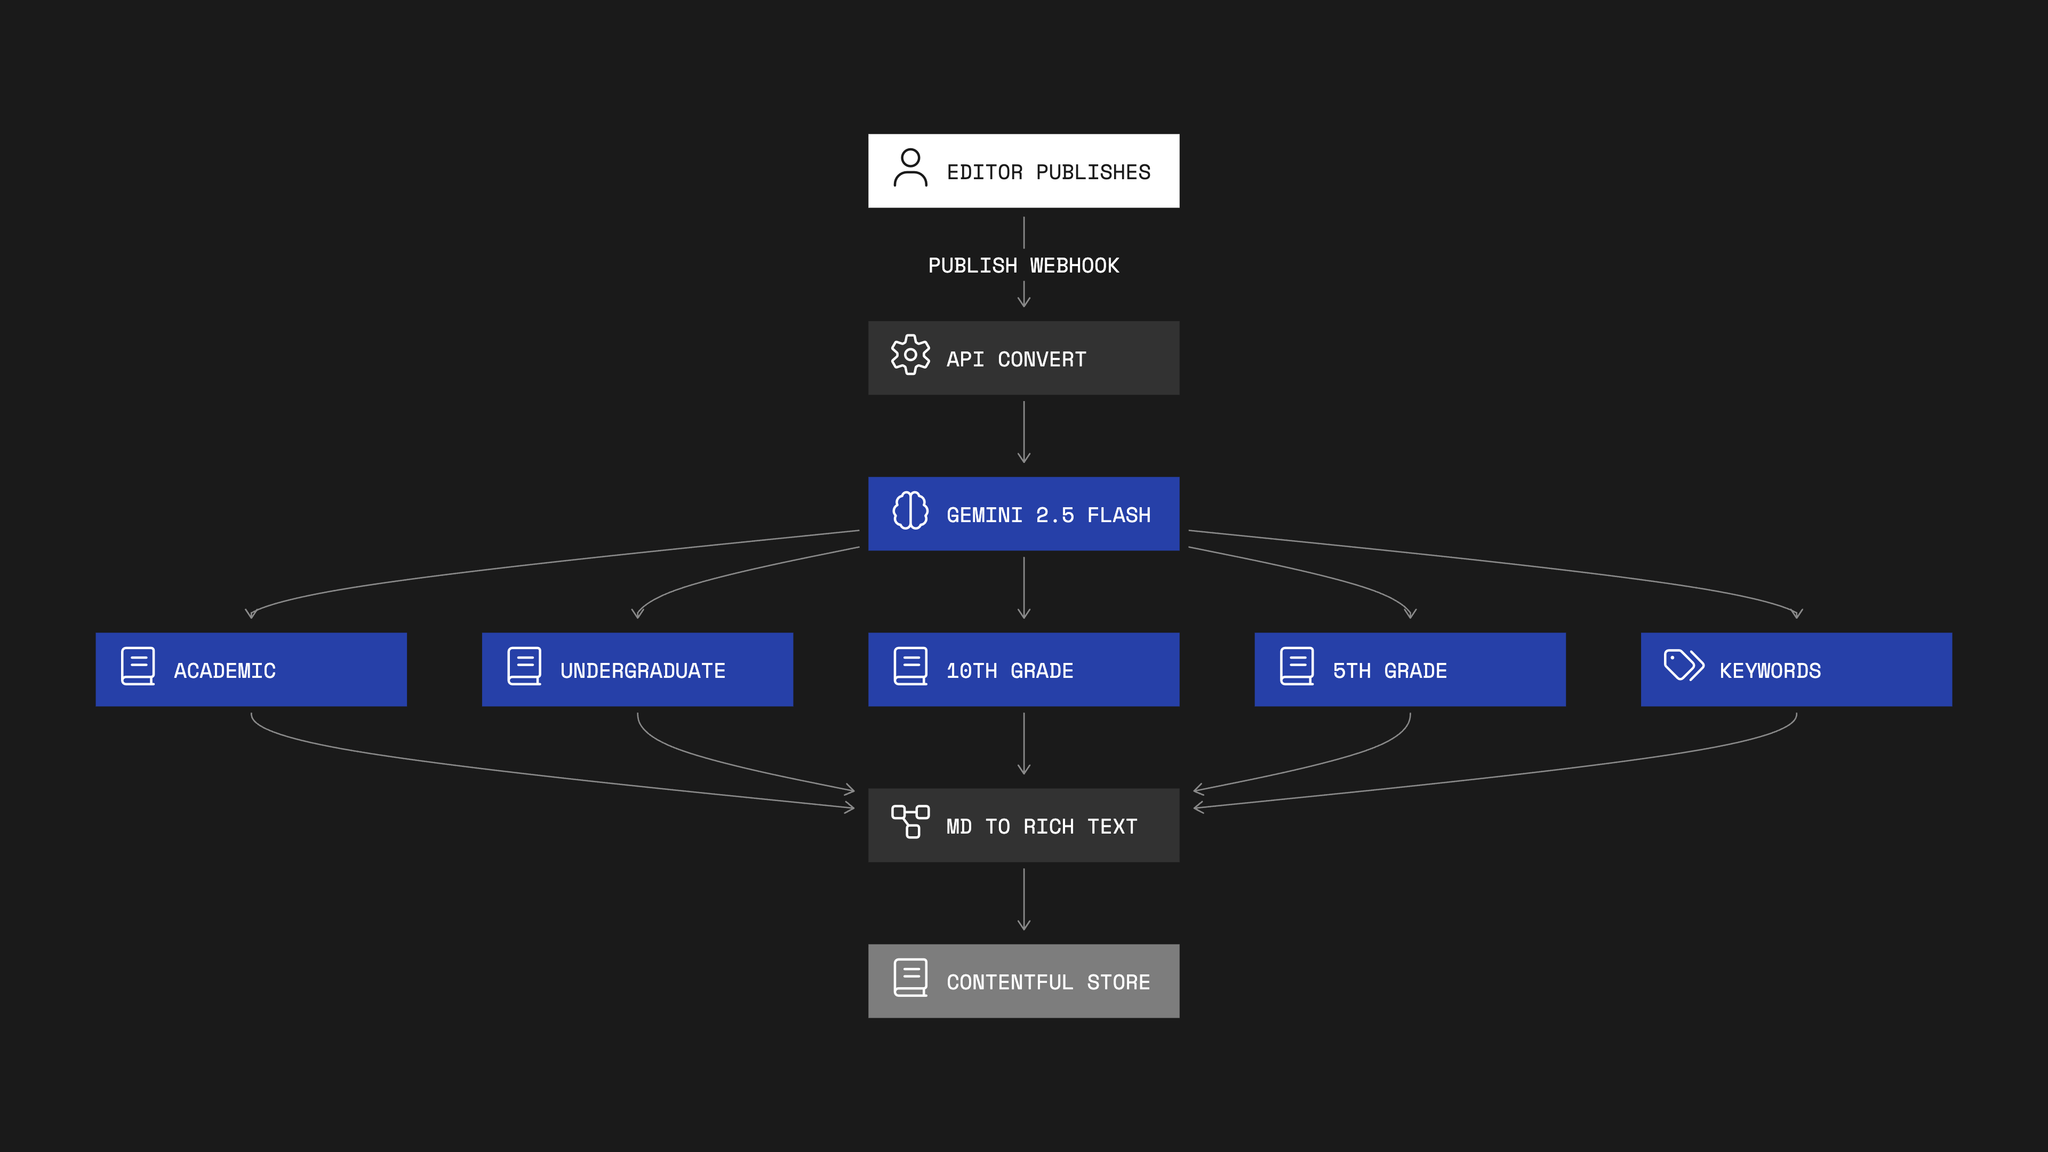
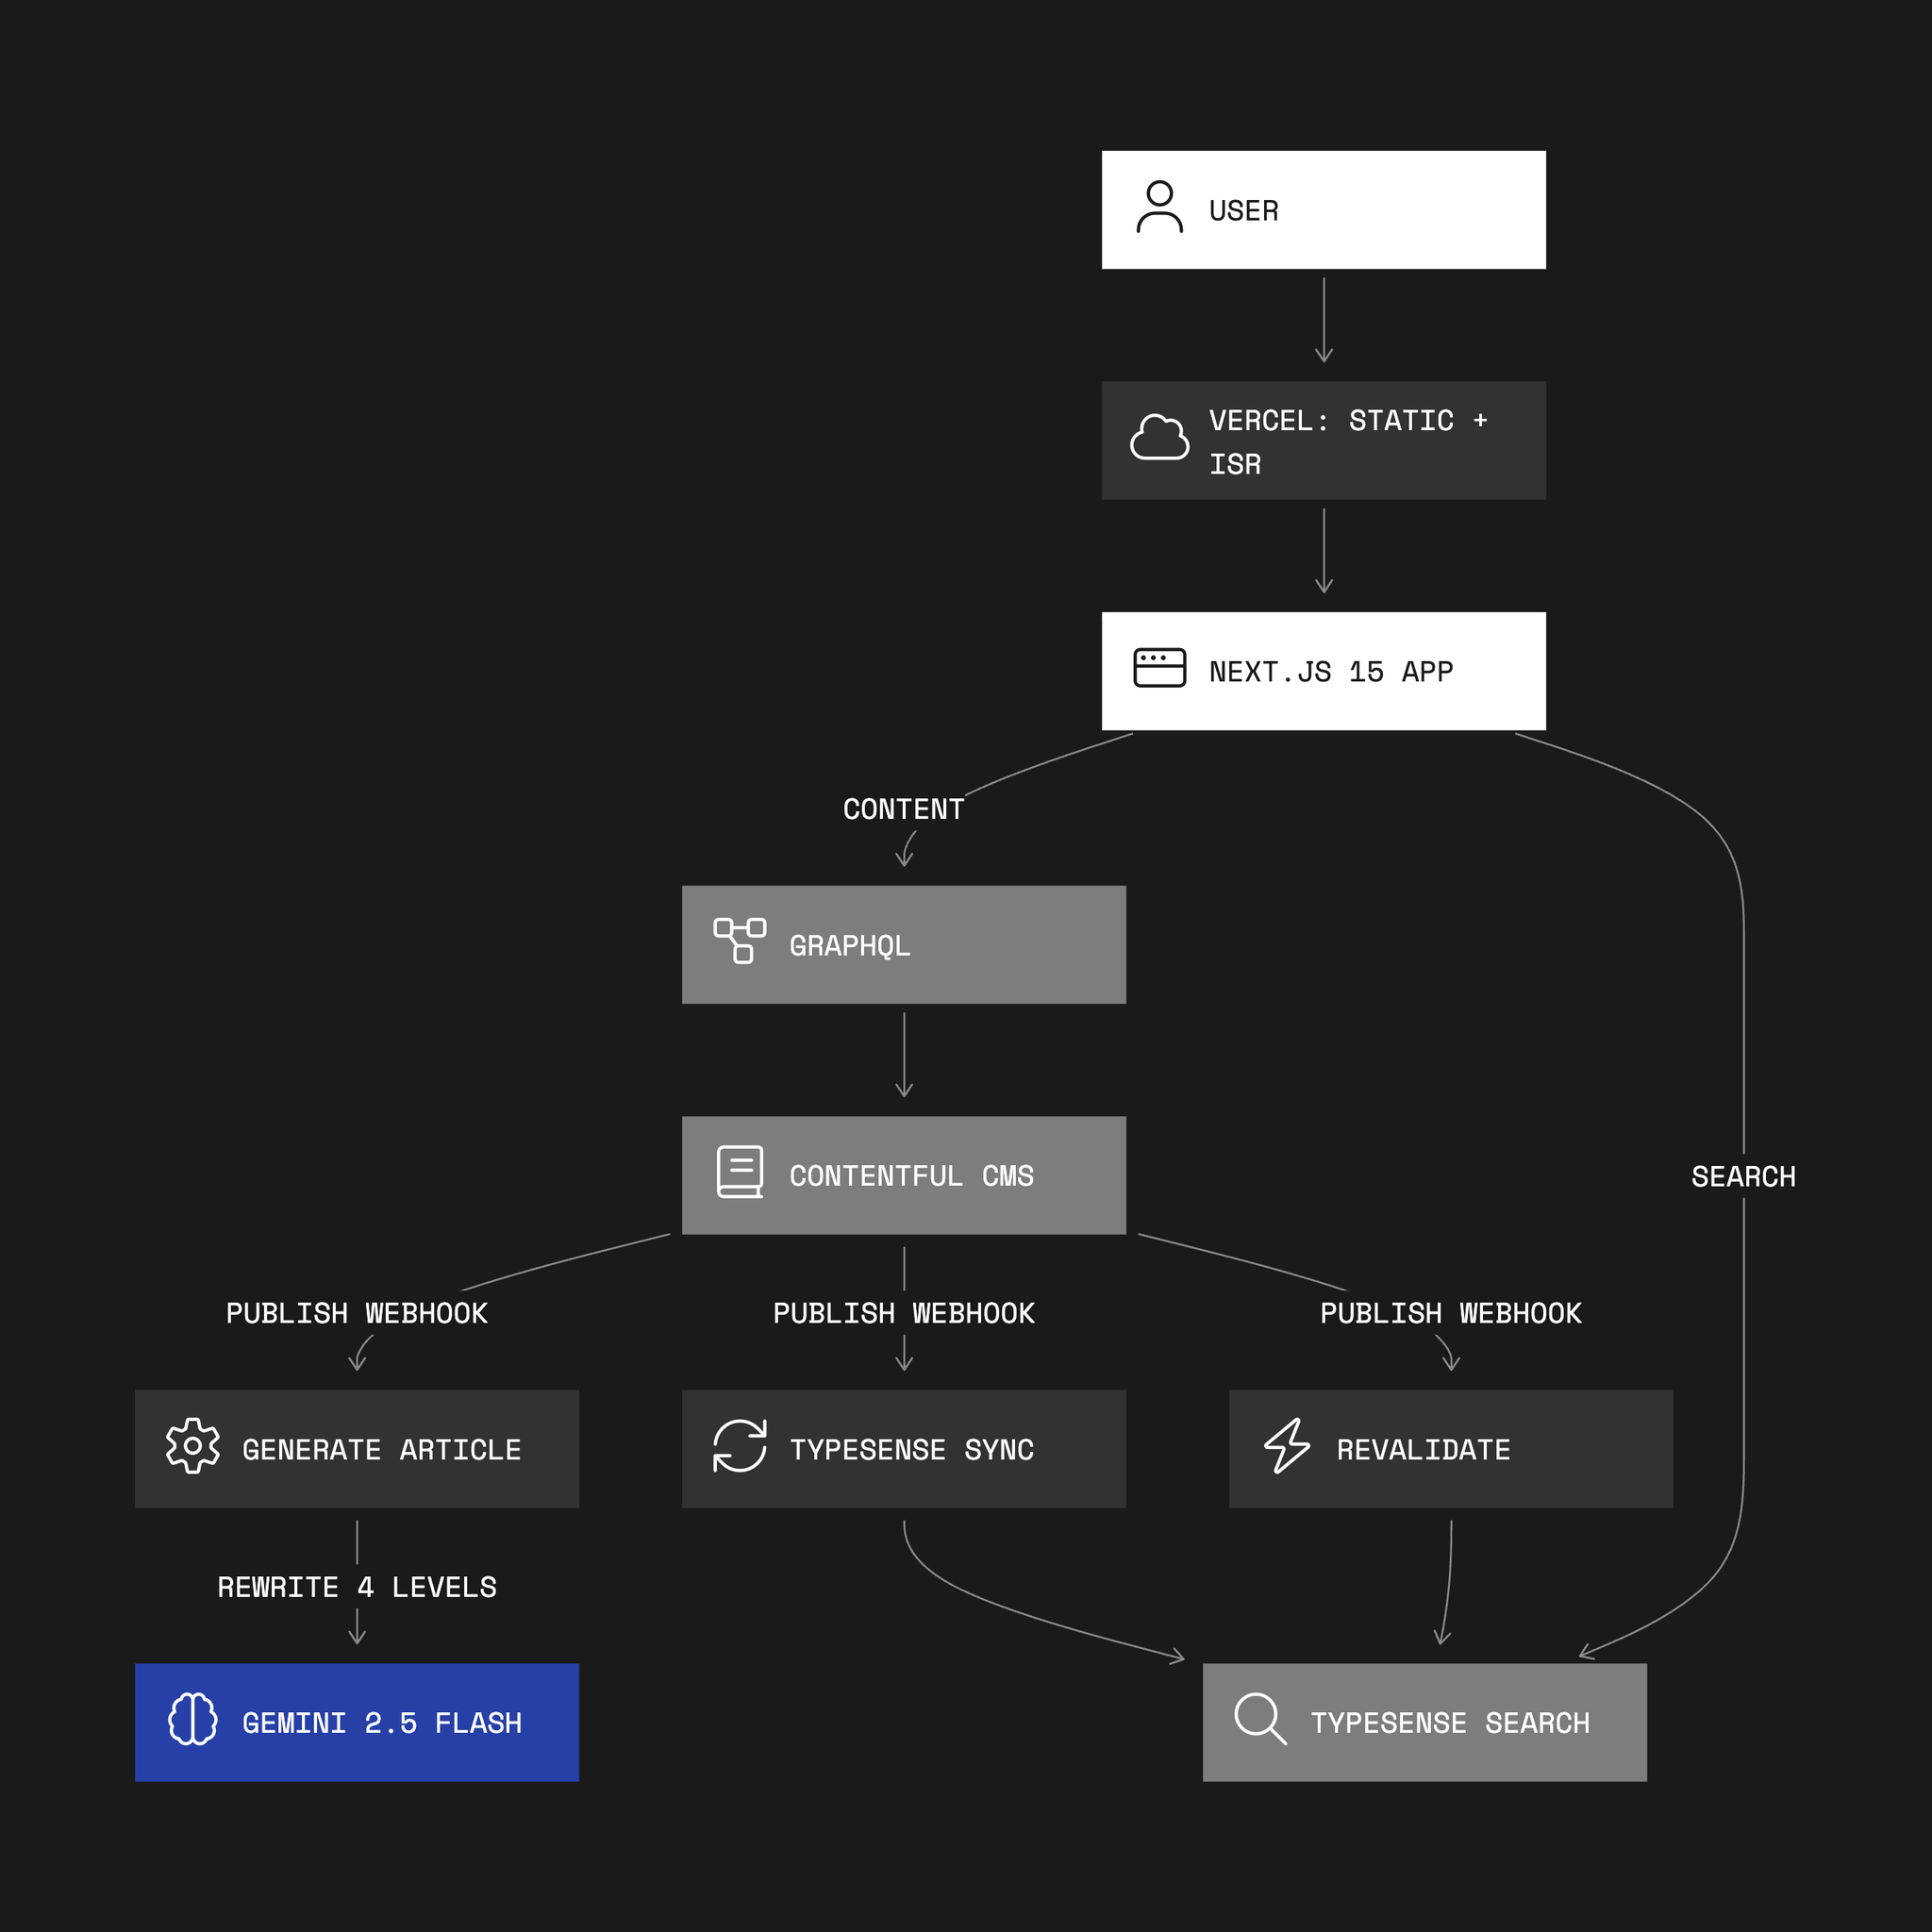
Two phases, kept apart on purpose. An editor flips a generate flag and publishes. A Contentful webhook fires, the document body is converted to clean Markdown, and Gemini 2.5 Flash rewrites it at four reading levels under fixed rules: third person, no citations, keep the structure, about five paragraphs. Separate passes pull keywords and write an at-a-glance summary. Each version is written back to Contentful as Rich Text in its own field, the original untouched.
Reading costs nothing. Pages are static on Vercel, and the slider swaps pre-stored text with no model calls.
The upgrade that made generation faster
The first SDK we used accepted a thinking-budget setting and ignored it. Every rewrite ran with the model thinking, about a minute per call, and the six calls per document ran one after another. Long documents hit the function timeout, and by mid 2026 a backlog of 167 articles and 29 amicus briefs sat stuck behind the generate flag.
In June 2026 we moved to Google's current GenAI SDK, which honours the setting, and ran the six generations concurrently. A document now finishes inside the 300-second limit. The change estimates about five times faster and cheaper per call. That figure comes from the engineering change, not from a production measurement.
Editors review before readers see it
Nothing generates automatically. An editor opts each document in. Since August 2026 the AI output lands in the Contentful draft rather than the published entry, and the entry republishes on its own only if it was clean when the job started. Anything else waits for a person.
A five-minute cooldown stops a double-fired webhook from running the job twice. If any of the six generations fails, the flag stays on so the next publish retries the whole set. The rewriting rules live in an editable prompt, not in model weights.
Search that understands the question
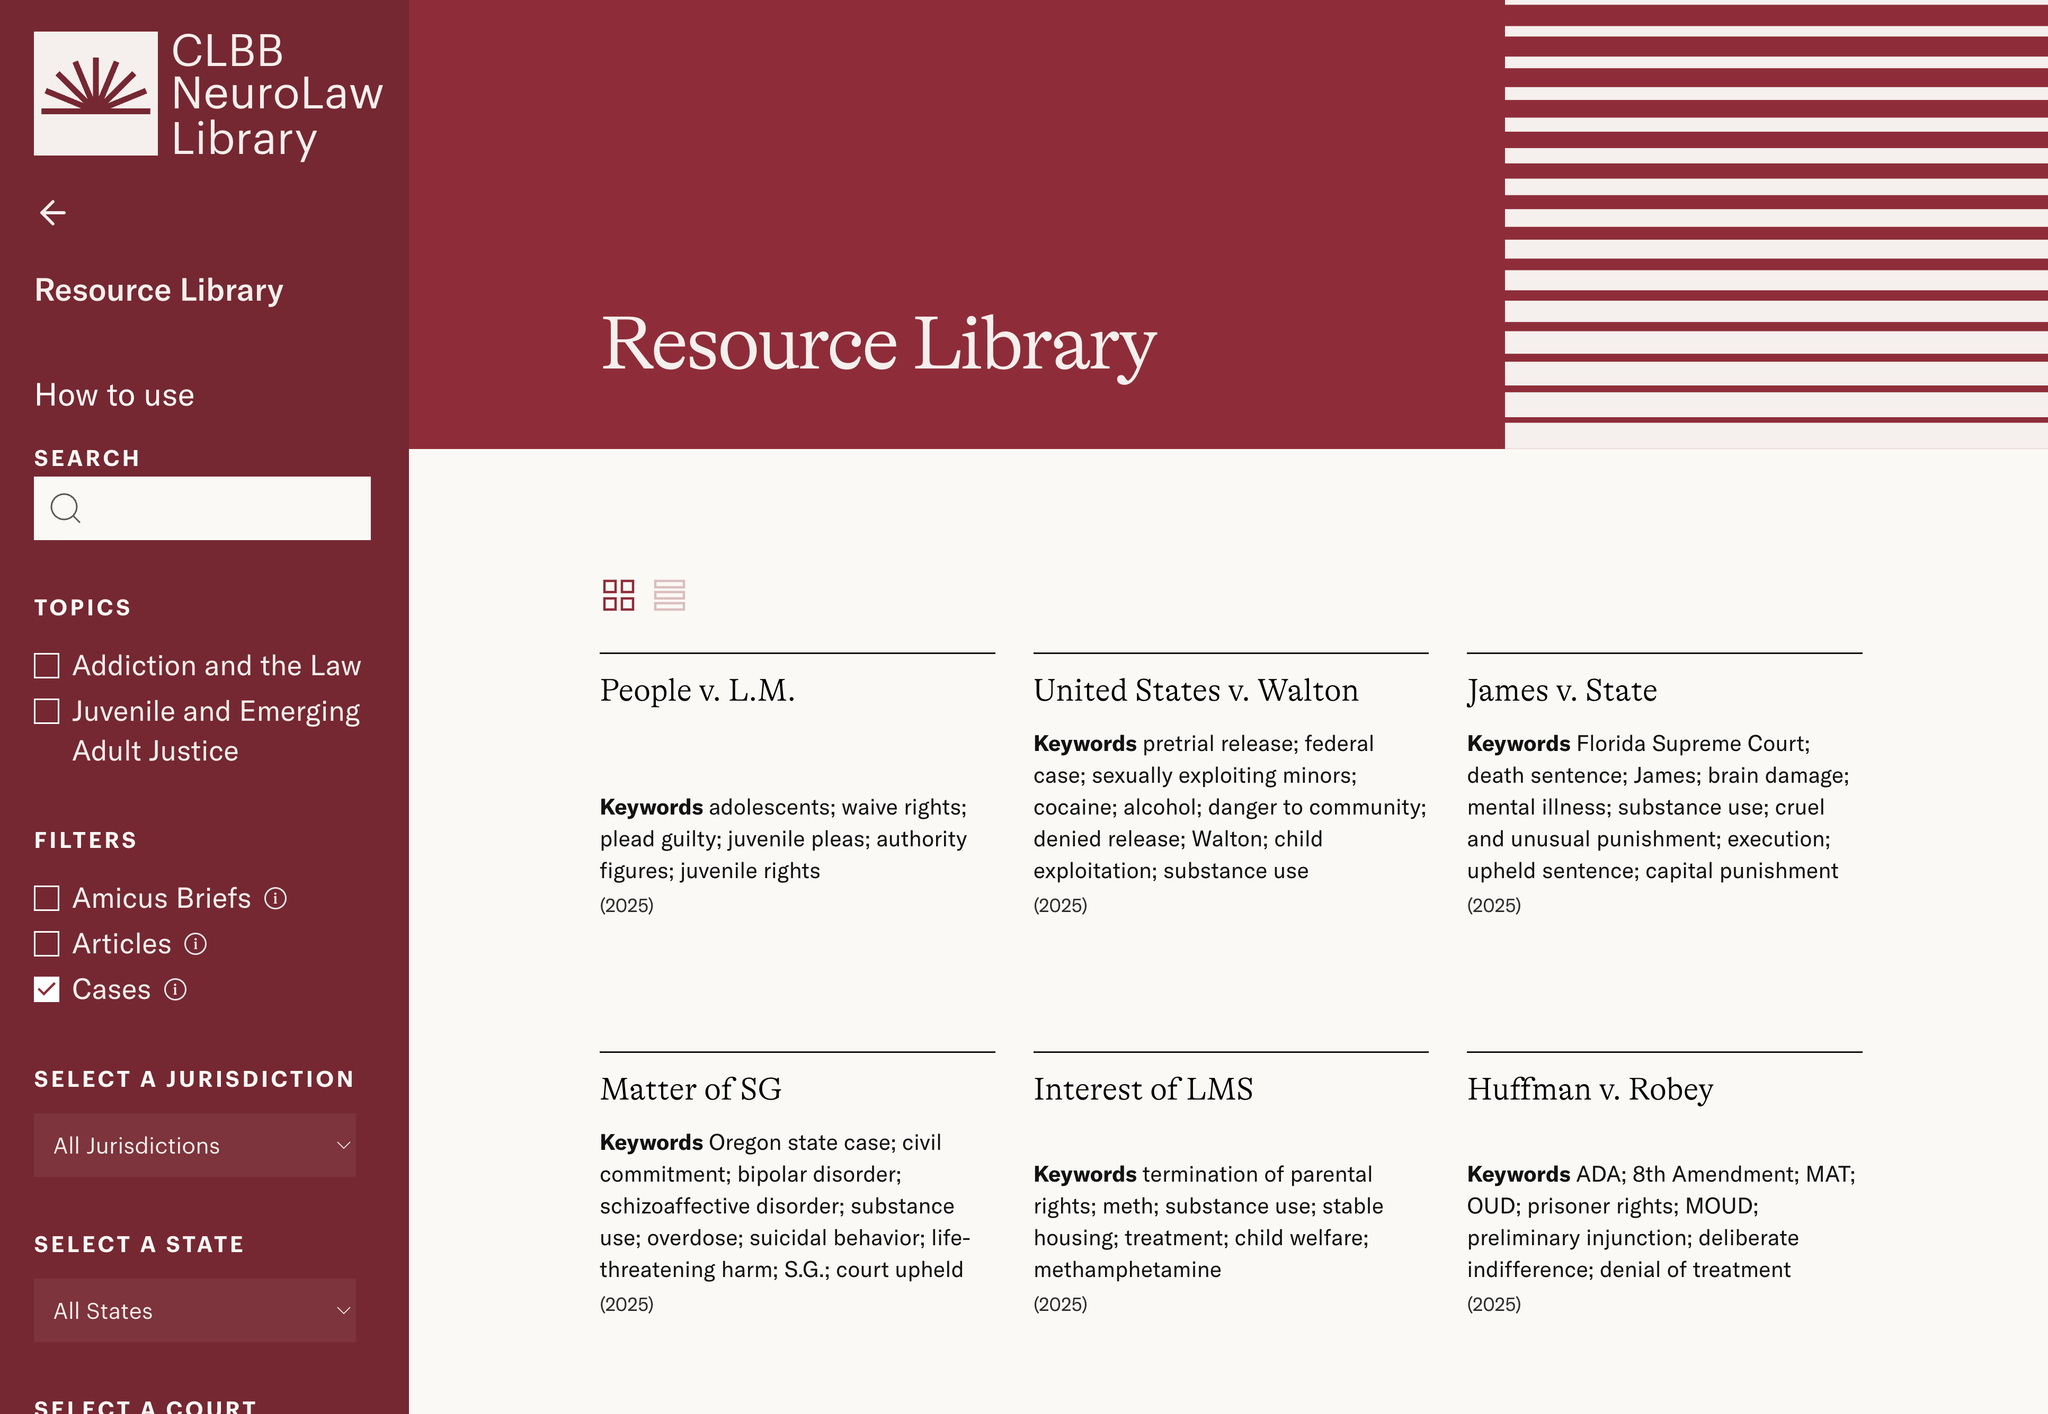
Readers think in questions, not content types. One Typesense index covers articles, briefs, cases, and affidavits with typo tolerance, synonyms, and filters for type, state, court, circuit, jurisdiction, year, and topic.
The August 2026 rebuild added semantic search. Each document gets a 3072-dimension embedding from Google's embedding model, built from its title, keywords, and the opening of its text, and a query combines that vector with keyword matching. The index now covers the body of each document, not only its title and keywords. A reindex builds a fresh collection, swaps an alias so the library never goes dark, and aborts if more than half the imports fail.
At a glance
Every document now opens with a one or two sentence summary for a general reader, written for its type: what a case decided, what an article found, what a brief argues, what an affidavit attests. The summary is capped at forty words and 240 characters. If the model runs long, it gets up to four more attempts before the shortest one is trimmed at a sentence boundary. A failure here never blocks the reading levels.
Can you trust the answer
The original is never replaced. The AI versions help people understand a document, they do not stand in for it. The original is always on the slider, and the quote and citation tools point back to it. You read the simple version, you cite the original.
Every resource carries citations in five formats: APA, AMA, MLA, NLM, and Bluebook.
Why we built it this way
Reading needs to feel instant, and documents are read far more than they're edited. Generating once keeps reading free, cost predictable, and output reviewable.
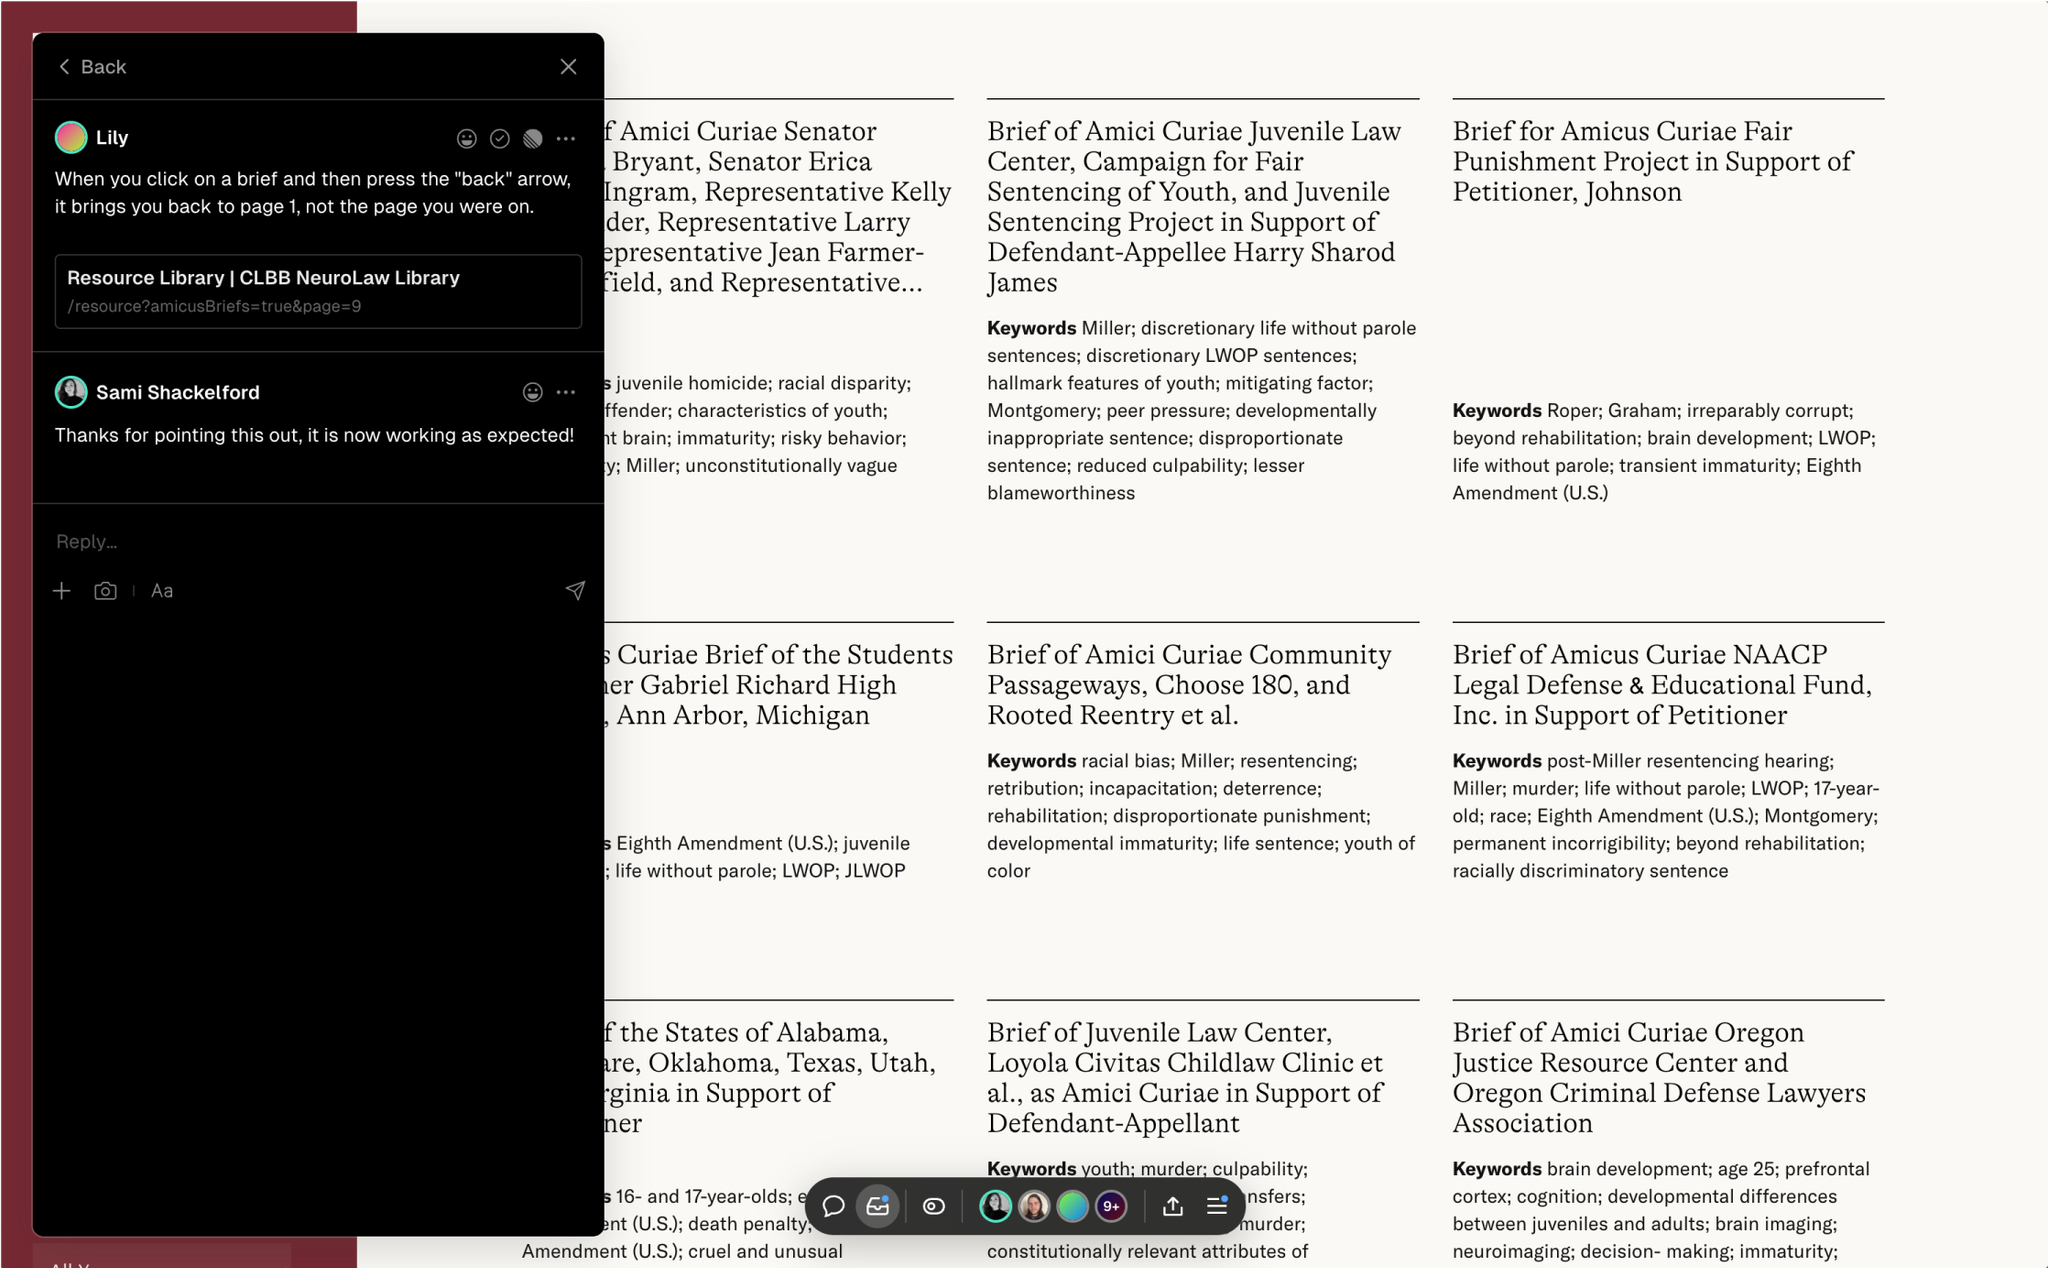
Review in the deployment, not in email
Acceptance testing ran on Vercel preview deployments with comments. The library team pointed at the exact element on the exact page, we replied in the thread, and the fix shipped to the same URL. Feedback never left the deployment.
Why it worked
The model was the easy part. The real work was getting thousands of documents into one place, making each one readable at any level, and keeping people in charge of what ships. Because the heavy work runs once at publish and the rules live in editable prompts, the library keeps growing without re-engineering.
The 2026 upgrade replaced the SDK, the search, and the review flow without changing what a reader sees: the same slider, now faster to fill.
Monogram was integral to designing the CLBB NeuroLaw Library at Massachusetts General Hospital. They are the best of the best.
Stephanie TabashneckFounding Director, CLBB NeuroLaw Library